DATA SCIENTIST · NEW YORK

I build models that answer business questions, and I measure whether they work.

$ focus:

Applied mathematician finishing an MS in Data Science at Pace University (December 2026). My projects cover fraud detection, churn prediction, A/B testing, SQL analytics and retrieval-augmented generation, each with code, held-out evaluation and a written recommendation.

fraud_detection.py

      
14public projects with code
3.89MS Data Science GPA
Batch topperBS Applied Mathematics
1.5 yrssoftware project management
01 / Work

Featured projects

Each one states a question, tests the answer on data the model never saw, and ends with what to do about it.

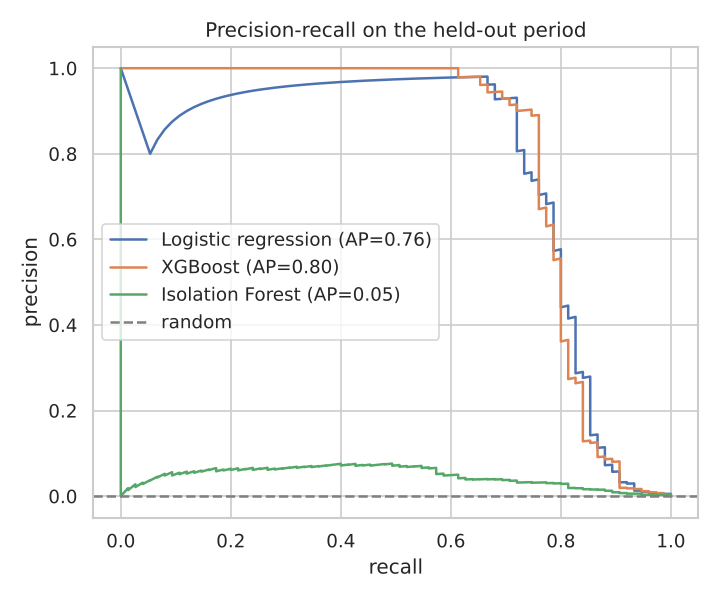
01Precision-recall curves for three fraud models

Credit Card Fraud Detection

Compares logistic regression, XGBoost and an unsupervised Isolation Forest on 284,807 transactions, scored on a later time period. Sets the alert threshold by dollar cost.

XGBoost catches 76% of fraud at 89% precision; cost on the test period drops from $7,729 to $2,708.
XGBoostIsolation ForestSHAPimbalanced data
View code →
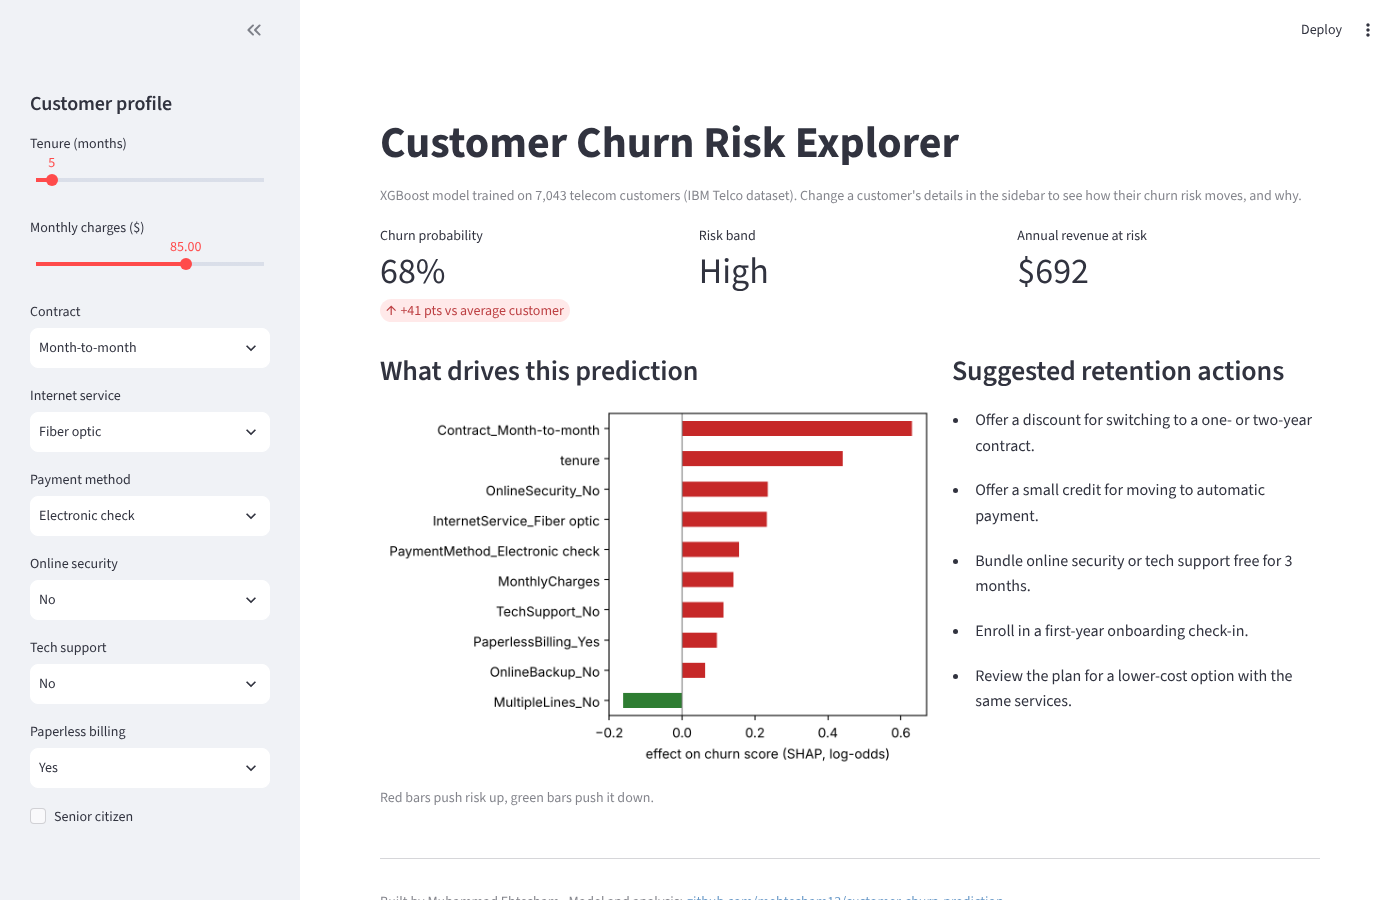
02Churn risk explorer app

Customer Churn Prediction

Predicts which of 7,043 telecom customers will leave, explains each prediction with SHAP and includes a Streamlit app that suggests retention actions.

Targeting the riskiest customers returns about 4x the value of random outreach.
XGBoostSHAPStreamlitprofit curve
View code →
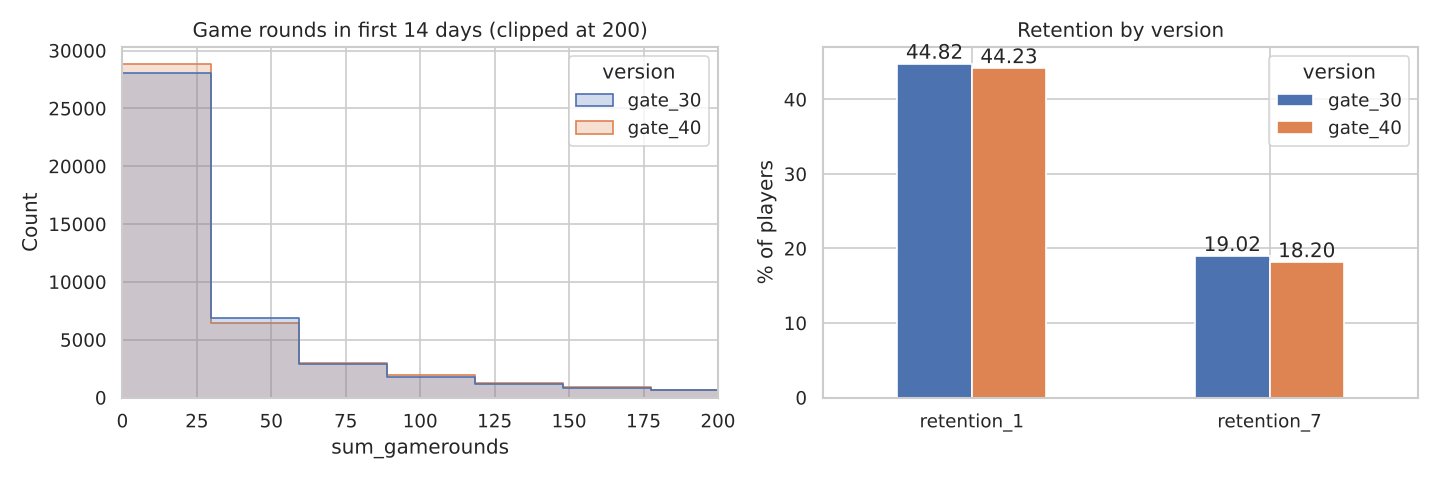
03Retention by test group

A/B Test: Mobile Game Gate

Analyzes a 90,189-player experiment with a sample-ratio check, z-tests, bootstrap, a Bayesian model and power analysis.

Keep the gate at level 30: moving it to 40 lowers 7-day retention by 0.82 points (p = 0.003, 99.9% Bayesian probability).
hypothesis testingBayesianpower analysis
View code →
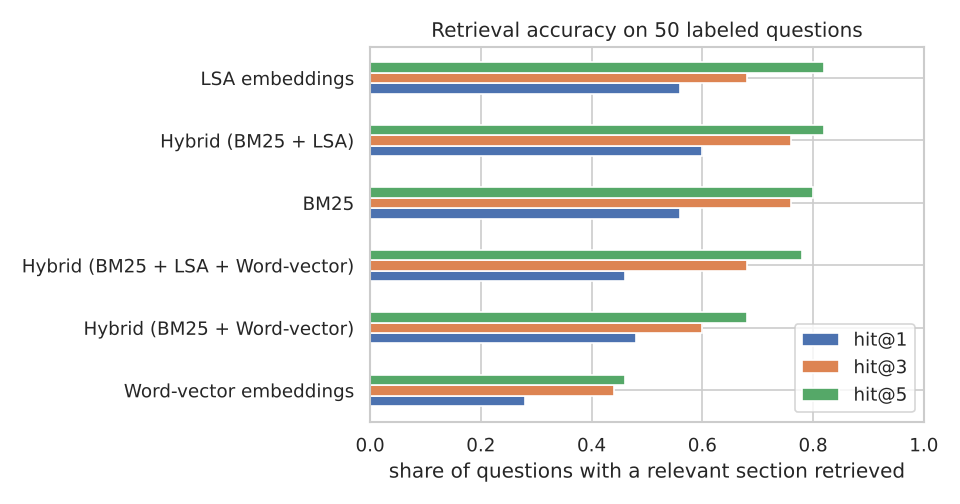
04Retrieval accuracy by method

RAG Question Answering

Answers questions about the scikit-learn User Guide with cited sources. Compares keyword, embedding and hybrid retrieval on 50 labeled questions, with a tested Python package and a Streamlit app.

Hybrid BM25 + LSA retrieval finds a correct section in the top 5 for 82% of questions.
RAGBM25embeddingspytest
View code →
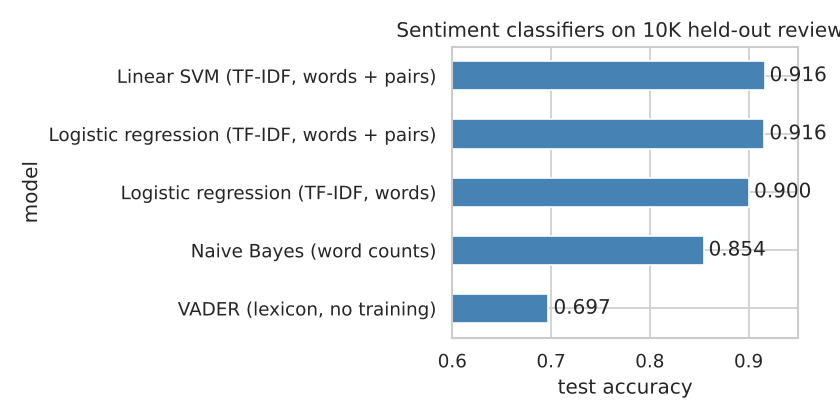
05Sentiment model accuracy

IMDB Sentiment Analysis

Classifies 50,000 movie reviews and compares a lexicon baseline with Naive Bayes and TF-IDF linear models, then studies where the model fails.

91.6% accuracy, 22 points above the VADER lexicon baseline.
NLPTF-IDFscikit-learn
View code →
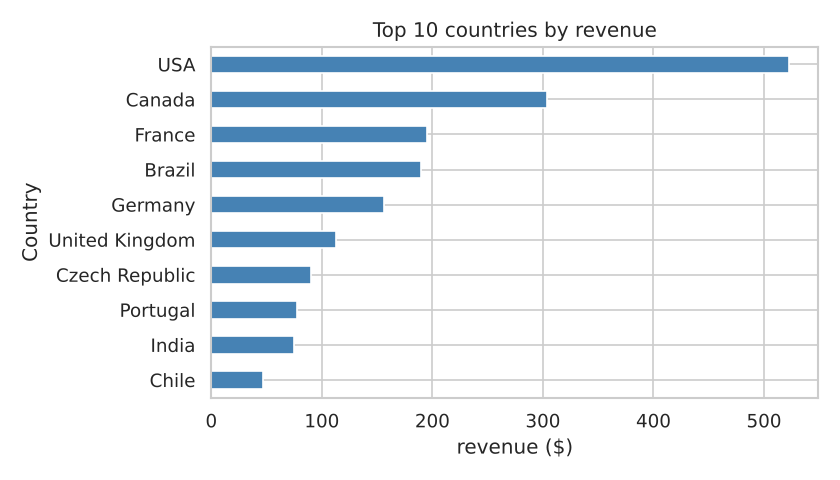
06Revenue by country

Music Store SQL Case Study

Eight business questions answered in SQL with CTEs and window functions, including RFM customer segmentation and a Pareto analysis of artists.

Found 14 lapsing high-value customers holding 25% of lifetime revenue.
SQLwindow functionsRFM
View code →

More projects

02 / Toolkit

Skills

What I use in the projects above.

Machine learning

scikit-learnXGBoostSHAPanomaly detectionimbalanced classificationtext classificationretrieval (BM25, embeddings)

Statistics

hypothesis testingA/B testingpower analysisbootstrapBayesian inferenceregressiontime series (Prophet, statsmodels)

Data

PythonpandasNumPySQL (CTEs, window functions)SQLiteNeo4j and Cypher

Delivery

Streamlit appspytestGitHub Actionswritten recommendations for non-technical readers
03 / Path

Education and experience

Mathematics first, then software delivery, then data science.

Expected Dec 2026

MS Data Science, Pace University, Seidenberg School

New York · GPA 3.89

Jun 2024 – Jan 2026

Project Manager, Innovate Technologies

Remote, part-time. Planned and delivered software projects with engineering teams.

2020 – 2024

BS Applied Mathematics, UET Lahore

Batch topper and silver medalist

Jun 2023 – Apr 2024

Mathematics Tutor, Sunshine Academy

Taught mathematics.

04 / Contact

Let's work together

Open to Data Scientist, Data Analyst, ML Engineer and risk or fraud analytics roles in New York or remote.

Send email LinkedIn GitHub
Email copied